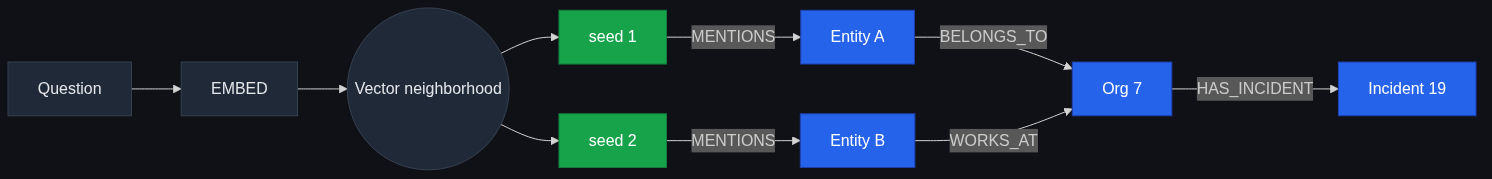
The most common architectural mistake I see in AI applications today is treating vector search as a complete retrieval system. It's not. Vector search is a complete similarity system, which is a different thing. Similarity is a useful signal. It is not a sufficient signal for most non-trivial retrieval problems, and the gap between "we found similar things" and "we found the right things" is exactly where vector-only RAG systems disappoint their users.
That gap closes when you add graph relationships to the retrieval path. Not as a replacement for the vector index — as a complement. The vector index is what gets you to the neighborhood; the graph is what tells you which streets in the neighborhood are actually connected to the one you came from.
This post is the case for adding graph relationships to your vector search, the four signals that say you need to, what "adding a graph" actually looks like operationally, and how to do it without bolting on a second database. The examples are SynapCores SQLv2 because that's the dialect where vectors and graphs live in one engine, but the argument applies whether you adopt our engine or stack two of them yourself.
The two questions retrieval can answer
Vector search answers exactly one question: what items in my corpus are most similar to this query item?
Graph traversal answers a different question: what items in my corpus are connected to this seed item, and along what relationships?
Both questions are useful. They are not the same question. A retrieval system that can only answer one of them is incomplete by design. The simple statement of the post is: most production AI applications need both, and people keep building systems with only one.
Four signals you've outgrown vector-only
I keep a running list from real production incident review. If your application hits any of these, you've reached the point where vector-only stops paying back.
1. The "what about X" question
A support copilot finds a relevant chunk: "Customer 42 reported MRI integration timeouts in March." The user follows up: "What about other accounts on the same plan?" The vector search has no way to express the same plan as a constraint. It can search for "Pro plan customers" semantically, but it can't follow the edge from Customer 42 to Plan to other Customers on the same Plan.
A graph traversal expresses this directly:
MATCH (c:Customer {id: 42})-[:ON_PLAN]->(p:Plan)<-[:ON_PLAN]-(other:Customer)
RETURN other
The vector index can't produce this answer because the relationship :ON_PLAN isn't in the embedding space. It's in the schema.
2. The "through whom" question
"How is this lead connected to our existing customers?" "Through what chain of approvals did this PR merge?" "What's the path of evidence from this transaction to the flagged ring?"
These all require the path itself to be in the answer. Vector search returns a set; the user wants a chain. Without graph traversal, the application has to reconstruct chains by repeated vector lookups — which is slow, lossy, and a lot of code.
3. The "at what time" question
A user asks: "Did the price of this product change in the last 30 days, and if so, what was it before?"
Vector search embeds the current text. It has no temporal model — versions and validity windows live in your schema, not in the embedding. Graph edges with valid_from / valid_to properties solve this cleanly:
MATCH (p:Product {id: 'abc'})-[r:HAS_PRICE]->(price:Price)
WHERE r.valid_from < datetime('30 days ago')
   OR r.valid_to > datetime('30 days ago')
RETURN price.value, r.valid_from, r.valid_to
ORDER BY r.valid_from DESC
You can simulate this in vector land by embedding multiple versions and filtering by timestamp, but you're outside the vector index doing that — and you've now lost the ranking signal that made vector search useful.
4. The "why did the agent say that" question
Audit. Every agent that ever ships hits this question. Users want to know which information led to a given answer. With vector-only, you can say "we used chunks 4837, 5012, 6219." With graph-aware retrieval, you can say "we walked Account 42 → BELONGS_TO → Org 7 → HAD_INCIDENT → Incident 19 → DESCRIBED_BY → chunk 4837." The path is the explanation.
If your product has any compliance or trust dimension — and most do, eventually — path-of-evidence beats chunk-id-list every time.
The "but I can just embed the relationships" objection
Every six months someone suggests embedding the relationships into the chunk text — "Account 42 belongs to Org 7" as a sentence in the corpus — so that vector search can find it. It doesn't work, for three reasons:
-
The combinatorial explosion is brutal. Every node-edge-node triple is its own sentence. A modest graph with 100k nodes and 1M edges becomes 1M sentences in the corpus. You're now embedding and storing a graph as text, badly.
-
The embedding model doesn't know the schema. Two sentences — "Account 42 belongs to Org 7" and "Account 42 reports to Org 7" — might embed nearly identically. A graph would never confuse
BELONGS_TOwithREPORTS_TO. Text-as-graph loses type information. -
You can't walk it. Even if you successfully retrieve "Account 42 belongs to Org 7," you can't follow the edge from Org 7 to another account in one query. You'd need a second vector search, then a third, then a fourth. That's traversal-as-RPC — slow, lossy, and a maintenance burden.
A graph is the right data structure for relationships. Flattening it into text and re-discovering it via vector similarity is the equivalent of storing a B-tree as a sorted CSV and re-discovering O(log n) lookups by linear scan.
What "adding a graph" actually means
This is where the conversation usually stalls because people think "adding a graph" means deploying Neo4j. It doesn't have to. There are three operational shapes:
Shape 1: dedicated graph database
Deploy Neo4j (or Memgraph, JanusGraph, etc.) next to your vector store. Two clusters, two query languages, two operational footprints, a sync job between them.
This works and the tooling is mature. The cost is the seams, as covered in GraphRAG vs Neo4j.
Shape 2: multi-model database with both
ArangoDB, OrientDB, and a few others bake both graph and document/vector capabilities into one engine. Lower operational footprint than two clusters. Smaller ecosystem, smaller community, smaller bench of integrations.
Shape 3: unified AI-native engine
The graph engine and the vector index share storage and a planner. Cypher and SQL operate on the same data; you can express the whole retrieval in one query.
WITH seeds AS (
  SELECT id FROM chunks
  WHERE COSINE_SIMILARITY(embedding, EMBED(:question)) > 0.6
  ORDER BY similarity DESC LIMIT 5
)
SELECT c.body, n.label, e.type, m.label
FROM seeds s
GRAPH MATCH (Chunk {id: s.id})-[e*1..2]-(m:Entity)
LIMIT 20;
This is what SynapCores does. It's not the only engine in this category — the category is growing — but it's the operational shape that has the lowest seam count.
The decision isn't whether to add graph relationships. It's which shape to add them in.